Complete ETL Guide: SFTP File Drops & Automation
An automated email workflow is only as useful as the data feeding it. If transaction records arrive after a scheduled send runs, the workflow may execute perfectly - and still miss the customers it was supposed to reach.
The video Complete ETL Guide: SFTP File Drops & Automation explores this problem in Salesforce Marketing Cloud: how to move from manually populated data extensions to workflows that respond when new files arrive.
Its larger lesson extends beyond marketing operations. File-based integration requires engineers to coordinate arrival detection, file preparation, loading, downstream actions, and recovery. Understanding those responsibilities is valuable for professionals moving into data engineering, where reliable ingestion often matters more than an impressive demonstration.
This article explains the workflow and adds a production-oriented perspective: what the demonstration proves, where its limitations are, and which design decisions deserve attention before customer communications depend on it.
The Core Shift: Trigger Work When Data Arrives
The demonstration starts with customer, transaction, and product information already stored in data extensions. That makes scheduled queries and communications straightforward: the workflow has something to process when it starts.
The challenge changes when transactions happen continuously and their records arrive later.
A file-drop workflow reverses the relationship:
- Time-driven workflow: A configured time starts processing.
- Arrival-driven workflow: A matching file starts processing.
Neither approach is universally better. A schedule can process recently arrived records if the workflow checks for them correctly. The important distinction is whether the business wants processing tied to a clock or tied to an incoming artifact.
Batch arrival is not the same as real-time processing
The video discusses transaction-driven communication but ultimately demonstrates batch delivery, including hourly files.
That distinction matters. If transactions accumulate for an hour before export, some customers may wait nearly that long before ingestion even begins. File detection, preparation, import, and communication add further delay.
A useful way to assess the design is:
Customer-facing latency = batch collection delay + transfer delay + processing delay + delivery delay
The video does not specify a latency guarantee. Treat this architecture as an arrival-triggered batch pipeline, not proof of immediate transaction delivery.
API-based integration is mentioned as another option, but its implementation is not specified in the video.
sbb-itb-61a6e59
Understand the Pipeline Before Configuring Activities
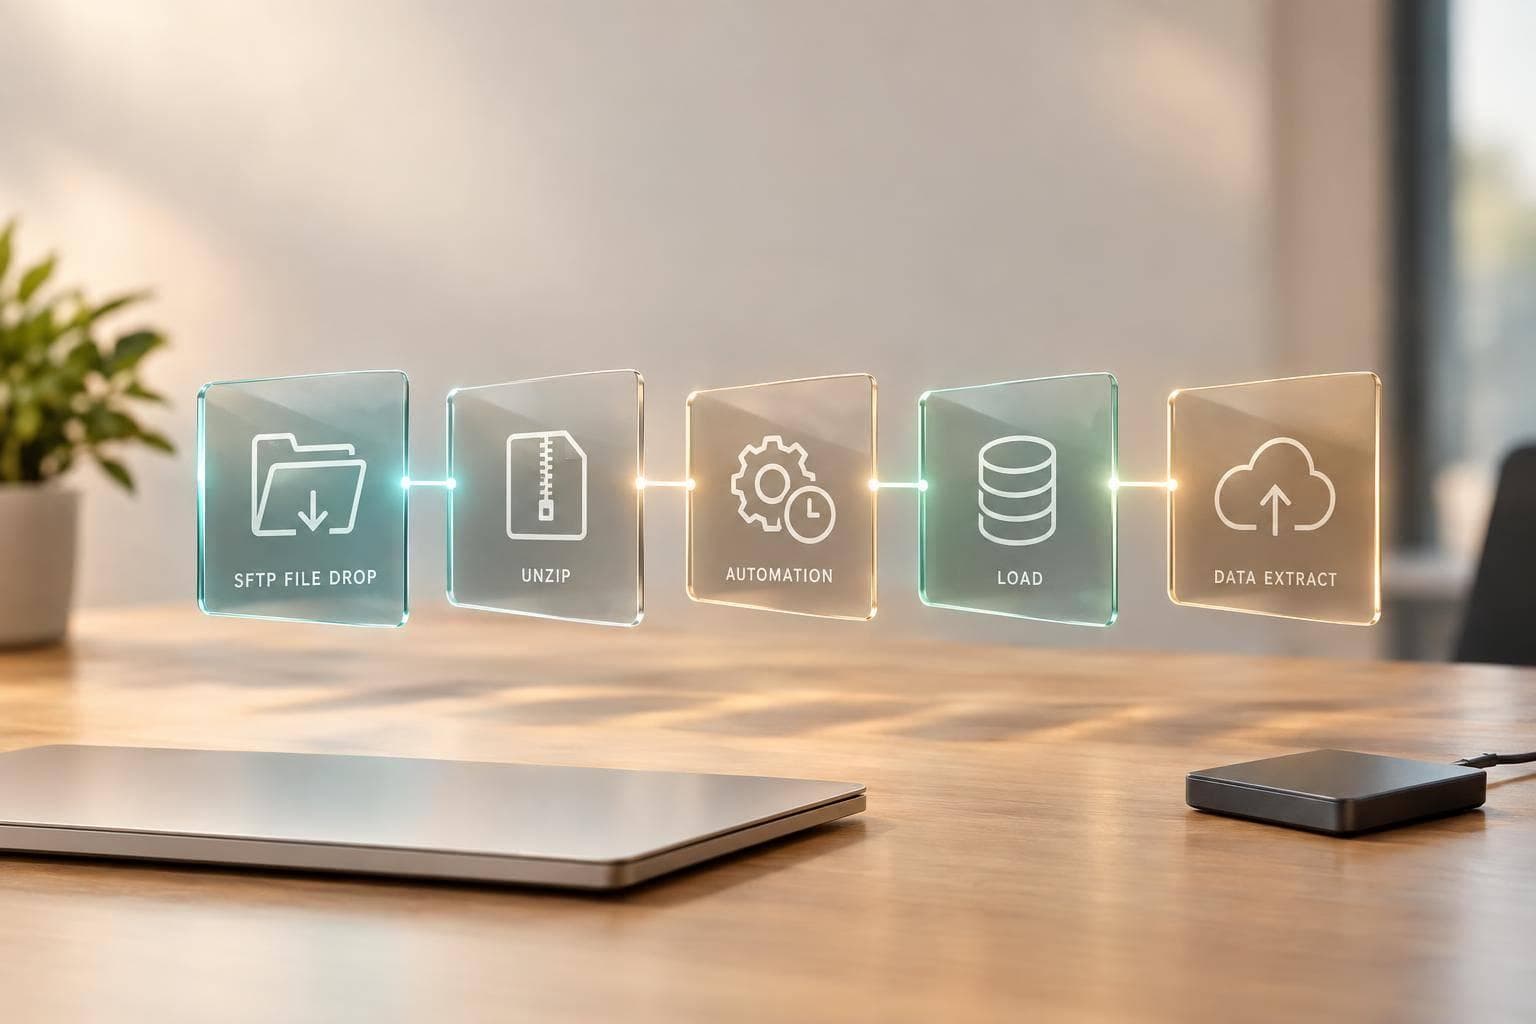
The demonstrated architecture can be summarized as:
Source system
    → Batch file
    → Marketing Cloud SFTP location
    → File-drop trigger
    → Optional file preparation
    → Import into a data extension
    → Downstream communication
    → Optional extraction and archival transfer
Each component has a separate responsibility.
| Component | Responsibility | What it does not prove |
|---|---|---|
| SFTP transfer | Delivers the file to the destination | That its records are valid |
| File-drop trigger | Starts a workflow for a matching arrival | That the correct file will be imported |
| File Transfer activity | Prepares supported compressed or encrypted files | That business fields are correct |
| Import File activity | Loads records into a configured destination | That sending to those records is appropriate |
| Communication activity | Performs the configured send | That every intended recipient received it |
| Extraction and archival steps | Preserve an output artifact | That recovery has been tested |
This separation is a central engineering insight: a successful upload is not a successful end-to-end pipeline.
Step 1: Define the Data Contract
Before building the automation, agree on what the source system will deliver.
The video uses a customer-profile file containing identifiers and communication fields, alongside separate transaction and product data. This highlights the difference between contact information and business context.
A customer profile may identify whom to contact. Transaction records establish why to contact them and what the message should contain. For invoices, linking those datasets correctly matters as much as loading them successfully.
A practical file contract should define:
- File naming convention and destination folder.
- Expected delivery frequency.
- Format, delimiter, encoding, and header structure.
- Required fields and identifier rules.
- Whether each file contains a complete snapshot or only changes.
- Compression or encryption requirements.
- Handling expectations for duplicates, late files, and invalid records.
These production details are not specified in the video. They are recommended design questions rather than demonstrated configuration.
Do not confuse sendability with data quality
The demonstration distinguishes a sendable customer-profile data extension from supporting transaction and product extensions.
The useful principle is that communication requires an appropriate recipient relationship and usable channel information. However, assigning a sendable role does not establish that an address is valid, that transaction joins are correct, or that a communication is authorized.
Keep those checks separate.
Step 2: Establish Secure File Delivery
The video uses an SFTP client to connect to a Marketing Cloud file location and upload a sample file. It identifies connection details such as host, username, password, and port.
A terminology clarification helps: SFTP is a secure file-transfer protocol, not a directory itself. The service exposes directories that clients access through that protocol.
For a learning exercise, manual upload demonstrates connectivity and triggering. For unattended operation, the source system must deliver files without a person dragging them into a folder.
Separate transfer security from file security
The demonstration later introduces ZIP files and encrypted files. These address different concerns:
- SFTP protects the transfer channel.
- Compression packages data and can reduce file size.
- Encryption protects file contents when the appropriate controls and keys are used.
A ZIP file is not automatically an encrypted file. Unzipping and decrypting are different operations.
The video does not specify credential rotation, host verification, access restrictions, or encryption-key management. Those controls should be reviewed before sensitive customer or financial data enters the workflow.
Step 3: Configure a Precise File-Drop Trigger
The demonstration configures an automation to watch an eligible SFTP folder and respond to a filename containing a particular identifier.
This proves an important point: data arrival can initiate processing without a fixed start time.
However, broad filename matching introduces ambiguity. If multiple feeds share a short identifier, an unrelated file could start the automation.
A clearer naming convention might be:
invoice_customers_20261002T140000Z_batch0042.csv
This is an illustrative recommendation, not a filename from the video. It communicates feed identity, time, and batch identity.
The exact supported matching syntax and configuration options are not specified in the video and should be checked for the account.
Align detection with file selection
The trigger answers:
Should this arrival start the workflow?
The import configuration answers:
Which file should this activity load?
Those are separate decisions. A workflow can start successfully and then fail because its import activity expects a different filename, extension, or location.
The demonstration exposes this problem when a ZIP archive arrives while the import still expects a CSV file.
Step 4: Prepare the File Before Loading It
For a directly usable CSV file, the workflow can proceed to import.
For the compressed example, the video inserts a File Transfer activity before the import. The activity unpacks the archive so the subsequent activity can load its contents.
The correct sequence is:
Detect archive
    → Prepare file
    → Import prepared data
The preparation step must finish before the load begins.
File preparation is only one kind of transformation
The video presents unzipping and decryption within its ETL explanation. These are important preparation operations, but they do not replace business-data transformation.
An invoice pipeline may also need to:
- Standardize dates and amounts.
- Validate required identifiers.
- Remove duplicate transactions.
- Join customer and purchase information.
- Reject records that cannot produce a valid invoice.
Those transformations are not demonstrated in the video.
For aspiring engineers, the distinction is useful: making a file readable is different from making its data trustworthy.
Step 5: Choose Import Behavior Deliberately
The Import File activity loads the prepared data into a selected data extension. The demonstration discusses different data actions and uses overwrite for its batch example.
That choice has architectural consequences.
| Data pattern | Possible loading approach | Main concern |
|---|---|---|
| Complete replacement snapshot | Overwrite | Existing records disappear |
| New events only | Append or add, as supported | Replays may create duplicates |
| Changes to existing entities | Update or add-and-update, as supported | Reliable keys are essential |
Exact behavior depends on the configured activity and destination.
Overwrite is a batch-processing decision
Replacing a working data extension can make each send operate on the newest batch. But it also means earlier data will no longer be available there.
Before choosing overwrite, decide:
- Where historical records will live.
- Whether the previous batch has finished processing.
- How a failed batch will be recovered.
- Whether an empty or incomplete file should replace valid data.
- How overlapping arrivals will be handled.
The video does not specify concurrency or recovery behavior. Those are important gaps to resolve before adopting the demonstration as a production design.
Step 6: Gate Communications on Successful Processing
The video extends the workflow by placing an email activity after import.
The basic dependency is sound: load the data before attempting to use it. The production question is whether import success alone provides enough assurance to send.
A stronger conceptual sequence is:
Prepare
    → Load
    → Validate
    → Identify eligible records
    → Send
    → Record processing outcome
Validation and outcome tracking are recommendations; their implementation is not specified in the video.
For invoice-related messages, useful checks include required transaction fields, correct customer associations, and protection against repeated processing.
Design for replay, not just first-time success
Files may need to be resent after an error. If replaying a batch causes the same invoices to be sent again, recovery creates a new problem.
A production design should therefore consider idempotency: repeating the same input should not unintentionally repeat customer-facing effects.
The video does not demonstrate duplicate detection. Batch identifiers, transaction identifiers, and processing records are possible design tools, but their suitability depends on the wider system.
Step 7: Preserve Data Without Assuming Export Equals Backup
The demonstration raises a practical issue: if later imports overwrite the working data, how do you preserve previous batches?
It introduces Data Extract activity for generating an output file, but the account shown lacks the desired extract option. The complete archival process is therefore not demonstrated.
Avoid treating that account-specific limitation as a universal pricing or availability rule. Supported extract types, enablement requirements, output locations, and subsequent transfer steps need verification for the actual environment.
An archive must support recovery
Keeping a copy is useful only if it supports the questions you will eventually need to answer:
- Which batch produced these records?
- What arrived originally?
- What changed during processing?
- Can the failed batch be replayed safely?
- Who may access the archived data?
- When should the archive be deleted?
A robust design may preserve the original incoming file as well as processed output. Retention requirements and recovery procedures are not specified in the video.
Test Failure Scenarios, Not Just Successful Uploads
The demonstration establishes that a matching upload can start an automation and populate a data extension. That is a useful first test, not a complete acceptance test.
Additional recommended scenarios include:
- Unexpected filename: Confirm that unrelated files do not start processing.
- Missing expected CSV: Confirm that the workflow fails visibly.
- Invalid archive: Confirm that preparation failure prevents downstream actions.
- Changed schema: Check how missing or incompatible fields are handled.
- Duplicate batch: Confirm that replay does not repeat communications.
- Empty file: Check the effect on an overwrite destination.
- Overlapping arrivals: Verify that batches do not interfere with each other.
- Send failure after import: Establish how recovery avoids reprocessing successful work.
Alerting, monitoring, and retry mechanisms are not specified in the video. A production implementation needs an explicit owner and response plan for failures.
Key Takeaways
- Use file-drop automation when batch arrival should initiate work, rather than assuming a fixed schedule matches data availability.
- Describe the design accurately: hourly file delivery is batch processing, even when the automation starts promptly after arrival.
- Align trigger matching with import selection so the workflow loads the file that caused it to start.
- Prepare archives before import, and distinguish compression from encryption.
- Choose overwrite, append, or update behavior intentionally, based on whether the feed represents snapshots, events, or changes.
- Validate before sending, especially when missing fields or incorrect joins could affect customers.
- Plan for duplicate delivery and replay so recovery does not create repeated communications.
- Verify archival capabilities in the actual account, and test whether retained files support recovery.
Conclusion
The video’s most useful contribution is showing how file arrival, file preparation, and data loading fit together in an automated workflow. It moves the discussion from "How do I upload this data?" to "How does the system respond when new data becomes available?"
For data-engineering professionals, the next step is to strengthen that working demonstration with clear contracts, validation, replay protection, monitoring, and recoverable archives. Those controls turn a successful file import into a dependable pipeline - and make the same architectural thinking useful well beyond Marketing Cloud.
Source: "Extract, Transform & Load (ETL) Explained | ETL Process in Data Engineering | Beginner to Advanced" - Peoplewoo Skills, YouTube, Jul 25, 2026 - https://www.youtube.com/watch?v=ZuIiEqAmOOA