How to Build an End-to-End PySpark Data Pipeline
How to Build an End-to-End PySpark Data Pipeline with Medallion Architecture
For aspiring data engineers, one of the hardest jumps is moving from isolated PySpark exercises to a pipeline that looks like something a real team would maintain. Reading a CSV into a DataFrame is useful. Building a layered pipeline that ingests raw files, preserves source truth, and prepares downstream-ready data is what starts to feel like production thinking.
That is the value of this beginner-focused PySpark project: it introduces an end-to-end pipeline pattern using medallion architecture inside Databricks. The video walks through a bakery sales example and shows how to structure the project from the ground up, starting with raw sources and moving toward curated data for analytics and AI use cases.
This article expands on that foundation. Rather than repeating the video, it explains why the design choices matter, where this approach fits in a modern data engineering workflow, and what professionals should pay attention to if they want to turn a beginner project into a portfolio-quality asset.
sbb-itb-61a6e59
Why This Project Matters for Early-Career Data Engineers
Many beginners learn tools in fragments:
- SQL in one course
- Python in another
- Spark in a separate tutorial
- Cloud concepts in theory only
What they often lack is a mental model for how the pieces connect.
This project helps close that gap by focusing on a practical question: How does data move from source files into structured layers that analysts, ML engineers, and AI engineers can actually use?
That framing is especially useful for mid-level professionals trying to transition into data engineering. Employers rarely hire for "can write one Spark command." They hire for people who understand:
- ingestion
- storage organization
- schema planning
- data quality handling
- transformation layers
- downstream usability
The bakery example is simple, but the architectural thinking is directly relevant to real-world systems.
The Core Architecture: From Source to Gold
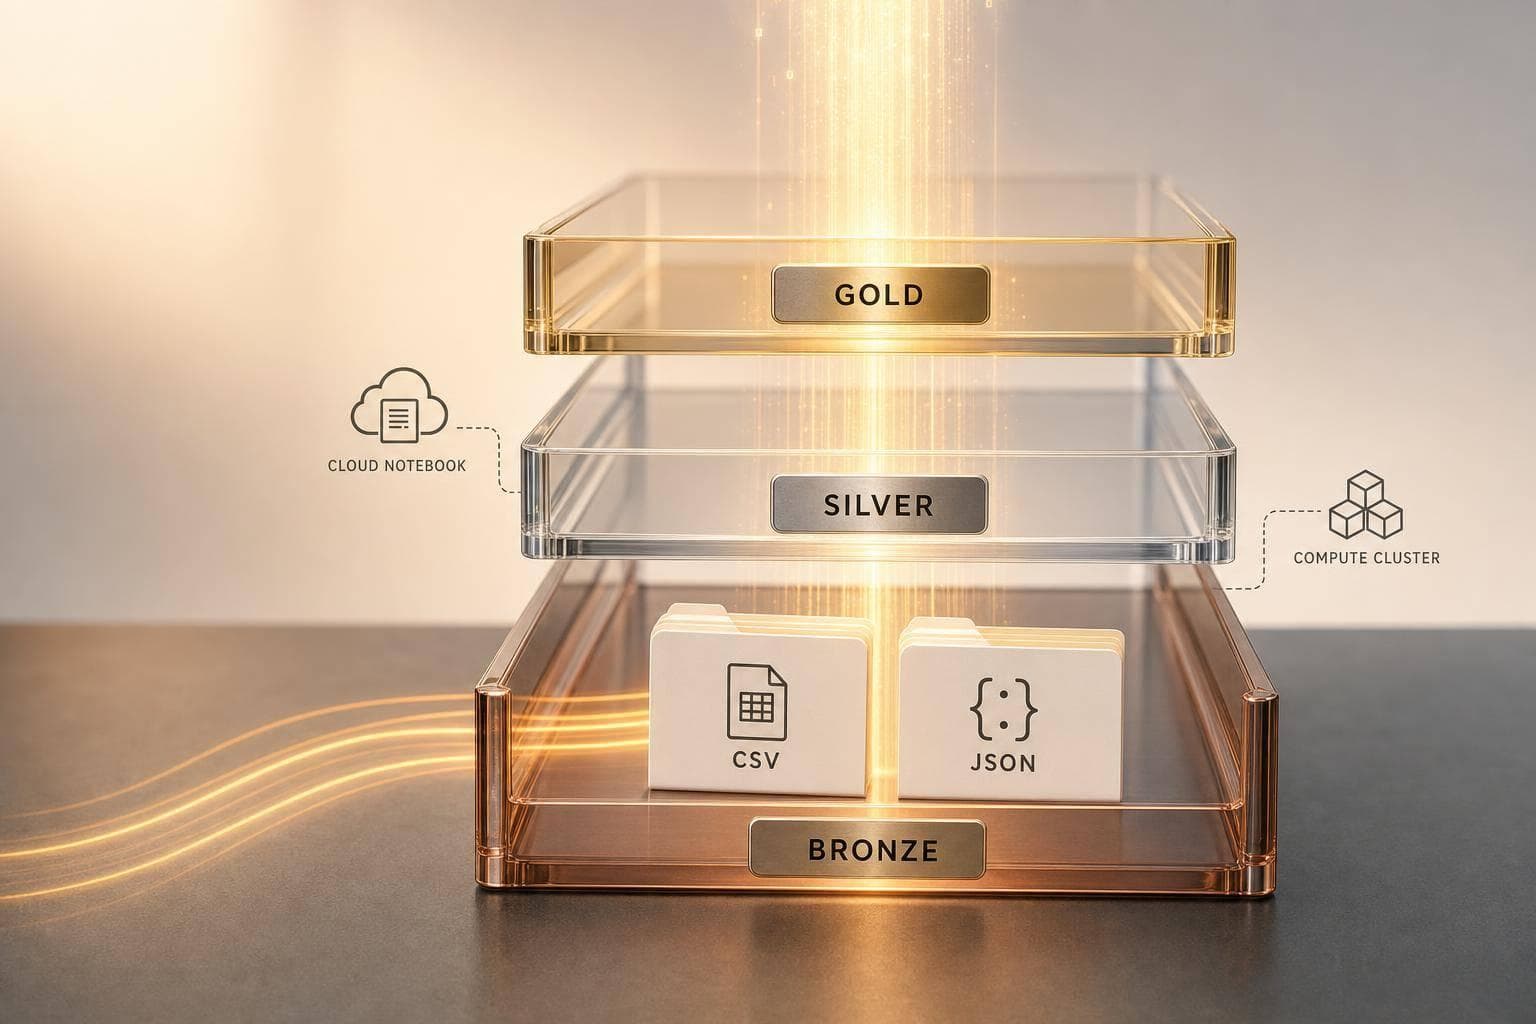
At the center of the project is a simplified medallion architecture. The video describes a flow like this:
- Source data arrives as CSV and JSON files
- Files land in a raw storage location
- Raw data is moved into a bronze layer
- Data is cleaned and validated in silver
- Refined, consumption-ready datasets are published in gold
In this implementation, Databricks volumes act as the raw landing zone, similar in concept to an object store such as S3.
What the Medallion Pattern Really Teaches
For beginners, medallion architecture is often introduced as just three layers. That is too shallow. The real lesson is about separating responsibilities.
- Raw landing/injection protects source fidelity
- Bronze creates a systematized version of raw data inside your platform
- Silver applies business-safe cleaning and validation
- Gold produces data products for consumption
This separation is valuable because it reduces confusion. If something goes wrong in a dashboard or model, teams can trace backward through layers instead of guessing where data changed.
One of the most important ideas from the video is the insistence on preserving raw data. That is not just a beginner tip. It is a professional best practice.
Why Raw Data Preservation Is Non-Negotiable
The tutorial emphasizes keeping source data unchanged in the initial stage. That principle deserves extra attention.
When data engineers overwrite or "fix" data too early, they create several risks:
- Loss of auditability
- Difficulty reproducing downstream issues
- Inability to reprocess with updated logic
- Confusion about whether errors came from the source or the transformation step
A good pipeline assumes that transformation logic will evolve. Requirements change. Validation rules improve. Business definitions shift. If the original data is preserved, you can rerun the pipeline safely.
That is why the raw landing area and bronze layer often exist even when they appear redundant. They serve different purposes:
- Landing zone stores the original delivered files
- Bronze organizes that data into the platform’s governed structure
In mature systems, this distinction can become critical for governance, incident response, and data lineage.
The Example Dataset: Bakery Orders and Customers
The project uses two source tables:
Orders table
The video outlines fields such as:
- order ID
- customer ID
- product
- category
- quantity
- unit price
- order timestamp
- order status
Customers table
The second table includes fields like:
- customer ID
- name
- city
- sign-up date
This is a smart beginner setup because it introduces a few foundational concepts without overwhelming complexity:
- fact-like transactional data in orders
- dimension-like reference data in customers
- a shared key via customer ID
- mixed data types including strings, numeric values, and timestamps
The video explicitly notes that star schema modeling is not the focus yet. That limitation is appropriate. For a first pipeline, it is better to master layered ingestion and transformation before jumping into dimensional modeling.
Schema Thinking: A Bigger Skill Than It Looks
One underrated part of the tutorial is the manual discussion of data types. That may seem basic, but it reflects an important professional habit: schema awareness.
The presenter walks through assigning types such as:
- string-like fields for names and categories
- numeric types for quantity and price
- timestamp for event time
Why does this matter?
Because schema choices influence:
- data quality checks
- aggregation correctness
- storage behavior
- query performance
- downstream model reliability
For example:
- If quantity is treated as text, sums become unreliable
- If timestamps are inconsistent, time-series reporting breaks
- If IDs are poorly typed, joins may fail silently or create duplicates
A beginner pipeline becomes much more credible when it shows that data types were chosen intentionally rather than left to chance.
Databricks as the Build Environment
The implementation happens in Databricks Free Edition, using the browser-based environment rather than local terminals or command-line setup.
For learners, this has several advantages:
- less friction getting started
- built-in notebook environment
- native Spark support
- easier focus on pipeline concepts instead of local infrastructure issues
The project treats Databricks as both the compute environment and the governance structure for organizing pipeline layers.
The Object Hierarchy Explained
The video spends time clarifying the namespace structure in Databricks:
- Catalog
- Schema
- Table or Volume
That hierarchy is more than a naming convention. It is how you define ownership and separation in a scalable environment.
In the tutorial’s design:
- one catalog holds the project
- multiple schemas represent the pipeline layers
- tables and volumes live within those schemas
The schemas created include:
- injection
- bronze
- silver
- gold
This design is simple, readable, and aligned with how many teams organize development projects in modern lakehouse platforms.
Why the "Injection" Schema Is Useful
The presenter uses the term "injection" where many practitioners might say ingestion or landing. The naming is less important than the purpose.
This schema contains the volume where source files first land.
Conceptually, that location acts like a controlled drop zone:
- CSV and JSON files arrive there first
- the files remain available in their raw form
- later logic reads from that volume into bronze
This is a good teaching choice because it makes storage boundaries visible. Instead of hiding the raw layer, the project makes it explicit.
For professionals building portfolios, that is helpful. Hiring managers often want to see whether a candidate understands the difference between:
- file arrival
- ingestion into a processing environment
- transformation into usable tables
This project demonstrates that separation.
Building the Foundation in Code
One of the strongest aspects of the tutorial is that it does not just explain architecture abstractly. It begins implementing it through code.
The project starts by creating variables for key names, including:
- catalog name
- schema names
- volume name
- landing path
This may look like a small Python convenience, but it teaches an important engineering practice: parameterization.
Instead of hardcoding every object name repeatedly, the notebook uses variables to make the setup:
- easier to read
- easier to update
- less error-prone
- more reusable across PySpark and SQL workflows
That pattern becomes increasingly important as projects grow. Today it is one notebook. Tomorrow it may be a deployment pipeline across dev, test, and prod.
SQL Inside PySpark: A Practical Choice
The video uses spark.sql(...) for setup tasks like creating schemas and volumes. That is a pragmatic move.
Even in PySpark-heavy projects, engineers often mix paradigms:
- Python for control flow
- SQL for DDL and familiar data manipulation
- Spark APIs for transformations
This is realistic. In production teams, rigid tool purity matters less than maintainability and clarity.
For a beginner, this also reinforces that PySpark work is not only about DataFrame transformations. It often includes environment setup, object creation, and storage management.
Error Handling as a Learning Signal
The tutorial briefly encounters a syntax issue while creating a volume. That moment is more valuable than it may seem.
Beginners often assume errors mean failure. In practice, debugging is part of normal engineering work. Reading the error message, identifying the typo, and rerunning the command is exactly how pipeline development happens.
A strong learning takeaway here is:
- create small units of code
- run them incrementally
- inspect outputs early
- validate objects in the workspace after each step
That habit prevents large, opaque failures later in the project.
Bronze, Silver, and Gold: What Should Happen in Each Layer?
The video gives a high-level description of each medallion stage. Here is a more practical interpretation for professionals.
Bronze: Controlled Raw Data
Bronze should preserve the source structure as closely as possible.
Typical bronze responsibilities:
- load source records
- preserve original columns
- add minimal metadata if needed
- avoid business-heavy transformation
Bronze is not where you should aggressively "fix" data. It is where you establish a trustworthy, queryable copy of what arrived.
Silver: Cleaned and Validated Data
Silver is where operational data engineering starts to matter most.
Typical silver responsibilities:
- type casting
- null handling
- deduplication
- filtering invalid records
- standardizing formats
- splitting out anomalies or outliers
The video mentions the idea of records missing required values such as date or time. That is a classic silver-layer concern. Records that violate expected rules may need to be quarantined, repaired, or separately tracked.
Gold: Business-Ready Outputs
Gold is the layer for consumers.
Typical gold responsibilities:
- business logic refinement
- curated marts
- analyst-friendly tables
- ML/AI input datasets
- stable, trusted metrics sources
The video correctly points out that downstream users may include analysts, ML engineers, and AI engineers. This is a crucial mindset shift for aspiring data engineers: your work is not complete when data loads successfully. It is complete when the data is reliable for use.
Data Curiosity: An Underappreciated Engineering Skill
One of the best ideas in the tutorial is the reminder that a data engineer should be "curious" about the data.
That is worth expanding.
Technical competence alone is not enough. Great pipeline builders ask questions such as:
- Does this field behave the way the name suggests?
- Why are there unexpected nulls?
- Are timestamps arriving in multiple formats?
- Is the customer ID actually unique in the customer file?
- Are prices always positive?
- Does order status follow a known set of values?
This habit is what prevents pipelines from becoming blind file movers.
For professionals moving into AI engineering, this is especially important. Poorly understood data creates downstream problems in feature engineering, prompt pipelines, retrieval systems, and model evaluation. Clean architecture begins with careful observation.
What the Video Covers Well and What It Leaves Open
The tutorial is intentionally beginner-friendly, and that is a strength. It focuses on setup, structure, and conceptual clarity. Still, for readers thinking beyond the first implementation, it helps to distinguish what is covered from what is not specified in the video.
Covered clearly
- medallion architecture basics
- source file ingestion using CSV and JSON
- preserving raw data
- creating Databricks catalog and schemas
- creating a landing volume
- using PySpark plus Spark SQL for configuration
- defining example source tables and data types
Not specified in the video
- exact transformation logic from bronze to silver and silver to gold
- partitioning strategy
- data quality framework beyond general outlier handling
- orchestration and scheduling
- testing approach
- CI/CD or deployment process
- production-scale performance tuning
- security and access controls
This distinction matters because many learners mistake a tutorial foundation for a complete production design. It is better understood as a career-building starter project rather than a full enterprise reference architecture.
How to Turn This into a Stronger Portfolio Project
If you are a mid-level professional trying to stand out, the basic pipeline is a good start. But to make it interview-ready, you should go one step further.
Consider adding these enhancements:
1. Data quality rules
Define explicit checks such as:
- quantity must be greater than zero
- unit price cannot be negative
- customer ID must exist in both tables when joining
- order timestamp must not be null
2. Quarantine tables for bad records
The video mentions outliers. Make that concrete by creating a separate silver table for invalid rows and documenting why each row was excluded.
3. Audit columns
Add ingestion timestamp, source filename, and processing batch ID where appropriate.
4. Documentation
Include a README that explains:
- architecture
- object hierarchy
- schema definitions
- transformation intent
- assumptions and limitations
5. Reproducibility
Parameterize object names and paths so the project can be reused in another workspace with minimal edits.
6. Business-facing gold outputs
Create one or two example gold tables such as:
- daily bakery sales by product category
- customer lifetime spend summary
Those additions make the difference between "I followed a tutorial" and "I understand how pipelines support decisions."
Key Takeaways
- Use medallion architecture to separate responsibilities across raw, cleaned, and curated data layers.
- Preserve raw source data first; do not clean or overwrite it too early.
- Model your storage hierarchy intentionally using catalog, schema, and table/volume organization.
- Treat bronze as controlled raw data, silver as the cleaning and validation layer, and gold as the business-facing output.
- Define schemas and data types deliberately so joins, aggregations, and timestamps behave correctly.
- Parameterize names and paths in code to make notebooks easier to maintain and reuse.
- Handle bad records explicitly instead of silently dropping them.
- Debug incrementally by creating objects step by step and validating each result in the workspace.
- Think about downstream consumers such as analysts, ML engineers, and AI engineers when designing transformations.
- Strengthen beginner projects with documentation, data quality checks, and curated outputs to make them portfolio-ready.
Final Thoughts
This PySpark project is valuable because it teaches more than syntax. It introduces a way of thinking about data engineering as a structured flow: source intake, raw preservation, layered transformation, and downstream readiness.
For beginners, that foundation is exactly what is needed. For experienced professionals transitioning into data engineering or AI-facing platform work, the deeper lesson is this: good pipelines are not just about moving data - they are about preserving trust while increasing usability.
The bakery example is intentionally simple, but the pattern scales. If you understand why the landing zone exists, why bronze stays close to the source, why silver handles quality, and why gold serves consumers, you are already learning the architecture behind much larger systems.
The next step is not just to replicate the project. It is to extend it with stronger validation, clearer business logic, and better operational discipline so it reflects the kind of pipeline a hiring manager would expect in the real world.
Source: "01 Data Engineering | End-to-End PySpark Bakery Project | Beginner 2026 - Design & Configurations" - Analytics with Henry, YouTube, Jul 28, 2026 - https://www.youtube.com/watch?v=KsB_dFhxTrM